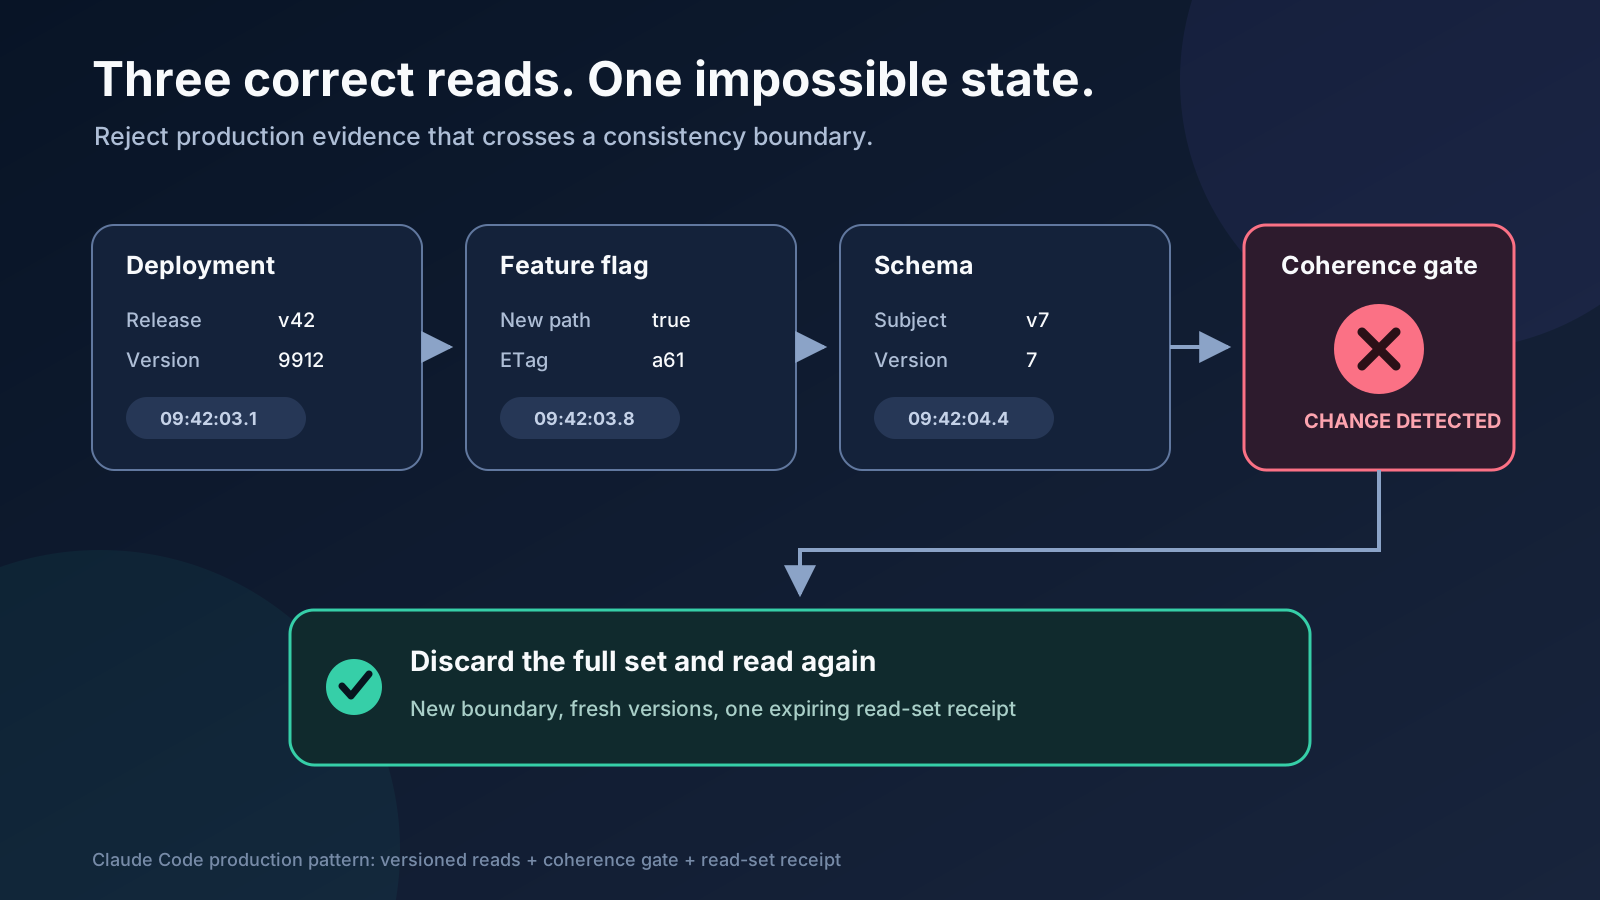
Three individually valid Claude Code MCP reads are rejected because their source versions form a mixed production snapshot

Reject a Claude Code plan built from a mixed snapshot

Claude Code can read three correct facts and still build a plan for a system state that never existed. Record a coherent read set and reject evidence that crosses a consistency boundary.

August 21, 2026 · 5 min · 898 words · Thomas De Vos
Read Reject a Claude Code plan built from a mixed snapshot
A Claude Code test denominator records expected, discovered, selected, executed, skipped, and missing tests before a review can pass

Make Claude Code report the tests it did not run

A green test result says little when the agent selected the wrong suite or skipped the risky path. Add a test denominator to every Claude Code review packet.

August 18, 2026 · 5 min · 940 words · Thomas De Vos
Read Make Claude Code report the tests it did not run
MCP tool output is labelled untrusted, reduced to evidence, checked against the original Claude Code scope, and recorded in a reviewable trace

Do not let MCP tool output rewrite Claude Code's instructions

An MCP response can contain instruction-shaped text that pushes Claude Code beyond its approved task. Put a trust boundary between tool evidence and agent authority.

August 17, 2026 · 6 min · 1129 words · Thomas De Vos
Read Do not let MCP tool output rewrite Claude Code's instructions
A Claude Code run pins an MCP capability manifest and stops when the live server schema, implementation, target scope, or side effects differ

Pin the MCP tool contract before Claude Code uses it

An MCP method can keep the same name while its schema, target scope, or side effects change. Pin a capability manifest so Claude Code cannot inherit a different tool after approval.

August 12, 2026 · 6 min · 1090 words · Thomas De Vos
Read Pin the MCP tool contract before Claude Code uses it
A Claude Code cost envelope that prices tool calls before execution, reserves budget at dispatch, records actual spend, and stops over-budget paths

Make Claude Code price the tool path before it starts

Token limits miss the expensive part of many Claude Code runs. A cost envelope prices search, MCP calls, evals, and retries before the agent can spend them.

August 11, 2026 · 5 min · 928 words · Thomas De Vos
Read Make Claude Code price the tool path before it starts
A Claude Code MCP permission delta showing one intended staging index allowed while production access, destructive DDL, another database, and role changes remain denied

Test the permission delta before widening Claude Code MCP access

A broader MCP grant may unblock one Claude Code task while authorizing unrelated production actions. Test what became possible and what must remain forbidden.

August 9, 2026 · 5 min · 897 words · Thomas De Vos
Read Test the permission delta before widening Claude Code MCP access
A Claude Code denial-path eval blocks a plausible production database write because the run has read-only permission

Test the Claude Code tool call that must be refused

Happy-path evals show whether Claude Code can use a tool. A denial-path fixture proves whether it refuses a plausible request that exceeds its approved authority.

August 7, 2026 · 5 min · 971 words · Thomas De Vos
Read Test the Claude Code tool call that must be refused
Diagram showing a bad Claude Code run becoming a replay case, an eval, a control change, and a safer next run

Claude Code evals should start with the run that scared you

The best Claude Code eval is not a tidy benchmark. It is the uncomfortable run your team does not want to repeat, captured as a replayable production control.

May 20, 2026 · 8 min · 1604 words · Thomas De Vos
Read Claude Code evals should start with the run that scared you
Diagram showing the operating gap between an AI POC and production AI

From AI POC to production: the part teams keep skipping

The AI POC is not the hard part anymore. The hard part is turning a promising demo into a service with ownership, evals, traces, cost controls, and a rollback path.

May 12, 2026 · 7 min · 1336 words · Thomas De Vos
Read From AI POC to production: the part teams keep skipping
Diagram showing metric-only LLM observability versus a replayable production AI trace

LLM observability is not a dashboard. It is a replayable trail.

A latency chart will not explain why an AI answer was wrong. Production LLM systems need traces, sources, tool calls, prompt versions, eval results, and human decisions.

May 10, 2026 · 4 min · 812 words · Thomas De Vos
Read LLM observability is not a dashboard. It is a replayable trail.